 Shahria Emon
Nested rollups outgrew version one.
Every edit anywhere in a task tree had to update every number above it, live. v1's architecture could not carry that.
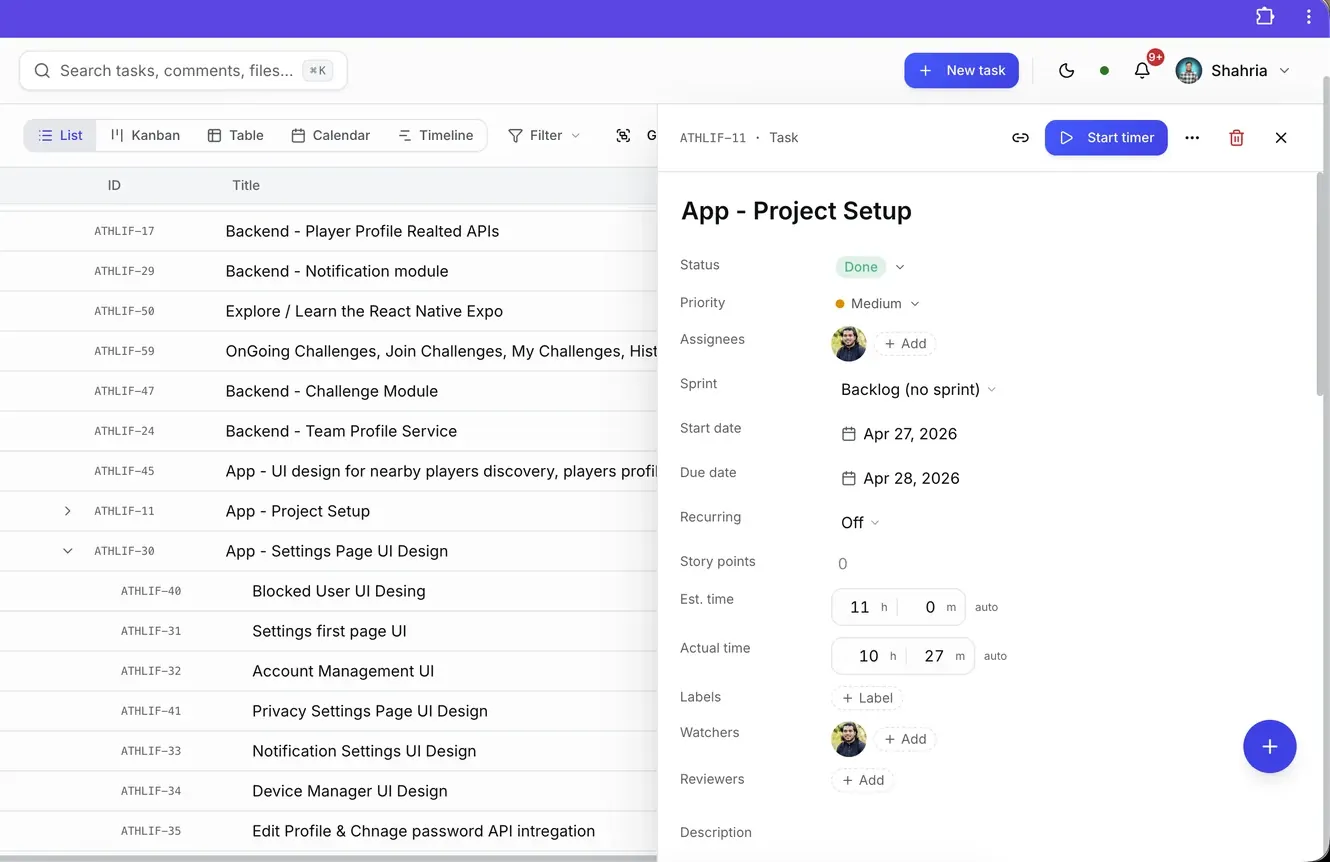
Scrumo v1 was the in-house build that proved the concept: a Scrum tool shaped around how Core Devs actually delivers. Tasks needed unlimited nesting, and every parent needed live rolled-up numbers: estimated time summed from children, actual time from timers and manual logs, story points, completion state.
That recursive recalculation grew heavier as data grew. Deep nesting slowed exactly the screens a PM lives in. The fix was not another patch but a new architecture, built around the rollup engine.
- Proved the concept and the workflow
- Rollup logic bound to the original architecture
- Recalculation slowed under deep nesting
- Ready for a new core
- 7 days from empty repo to working core, solo
- Rollup engine designed first
- Deep nesting with instant rollups on live data
- Runs Core Devs delivery every day, 3 workspaces
Empty repository to internal demo.
The decision that made the week possible: build the hardest thing first, not last.
The rebuild started from a written spec, not from code: a full SRS of 237 requirements, a coded design prototype as milestone one, then vertical slices with tests at every step. The rollup engine shipped before the features that depend on it, instead of being bolted on at the end like v1.
First commit, spec locked
SRS V3.0: 237 requirements, 196 scoped for the MVP. Multi-tenant architecture with PostgreSQL row-level security decided on day one.
All 23 screens, coded and signed off
Not mockups: a working React 19 + Tailwind prototype of every screen. Auth and the multi-tenant core passed UAT the same day.
Rollup engine live
Nested subtasks, time tracking and the full rollup system, summing up the tree instantly. Projects, sprints and the task core landed the same day.
First internal demo
Files, comments, notifications and reporting on top. The team started planning real sprints in it, and it never went back on the shelf.
Why the rollup engine works this time.
One canonical rollup service on the server. The frontend never computes a rollup, it only renders what the server resolved.
v1's limit was architectural, so the v2 answer had to be too. Every write that can affect a tree, from the UI, a bulk operation, a timer or an API call, flows through the same recalculation path inside one transaction.
Two rules keep it honest. Display values never drift from source data: when someone corrects a task's actual time, the engine reconciles the underlying time entries in the same transaction, so the timesheet and the task can never disagree. And every derived number has exactly one implementation, pinned by an integration test suite, so regressions surface before deploy, not in a sprint review.
A full Scrum suite, not a toy.
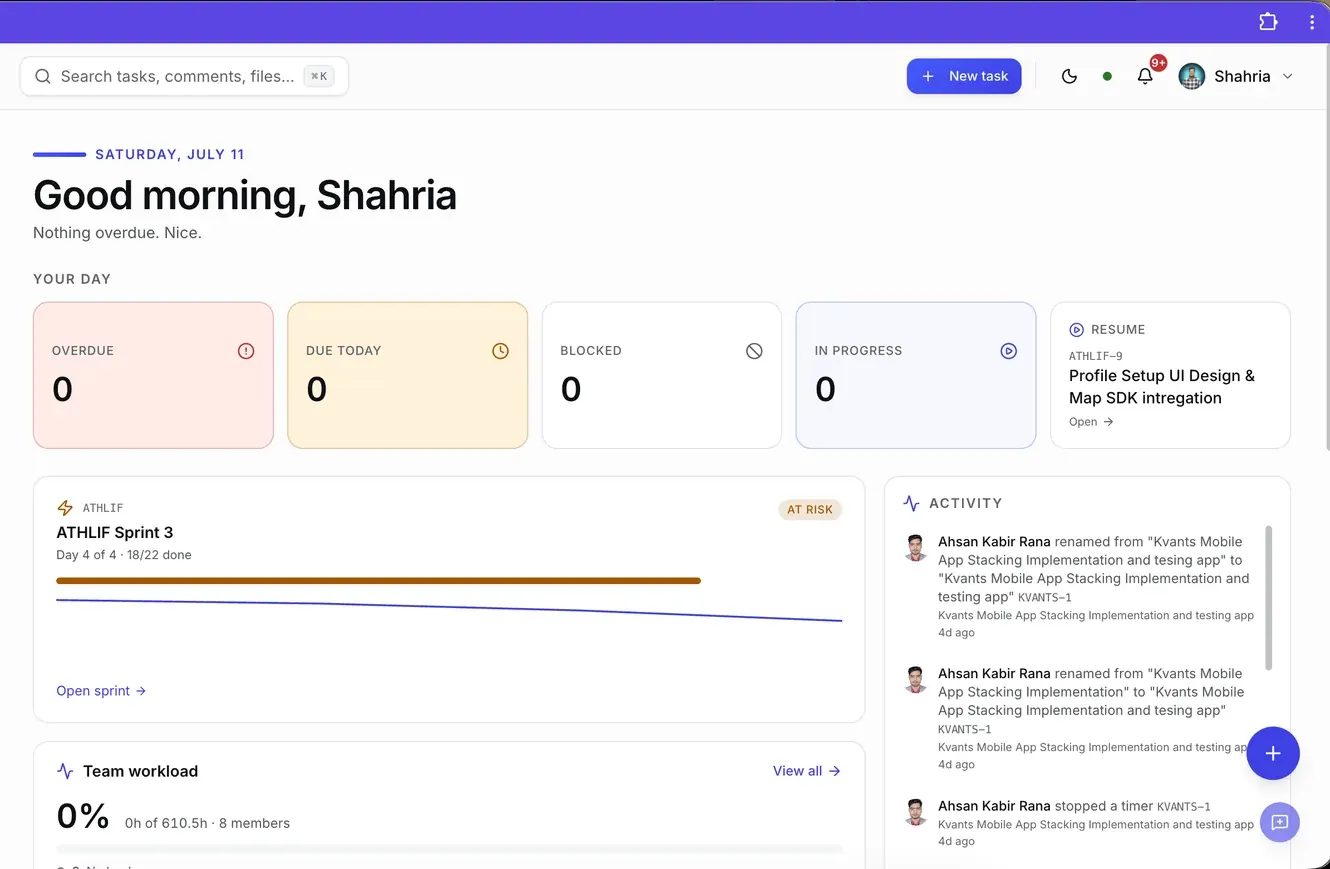
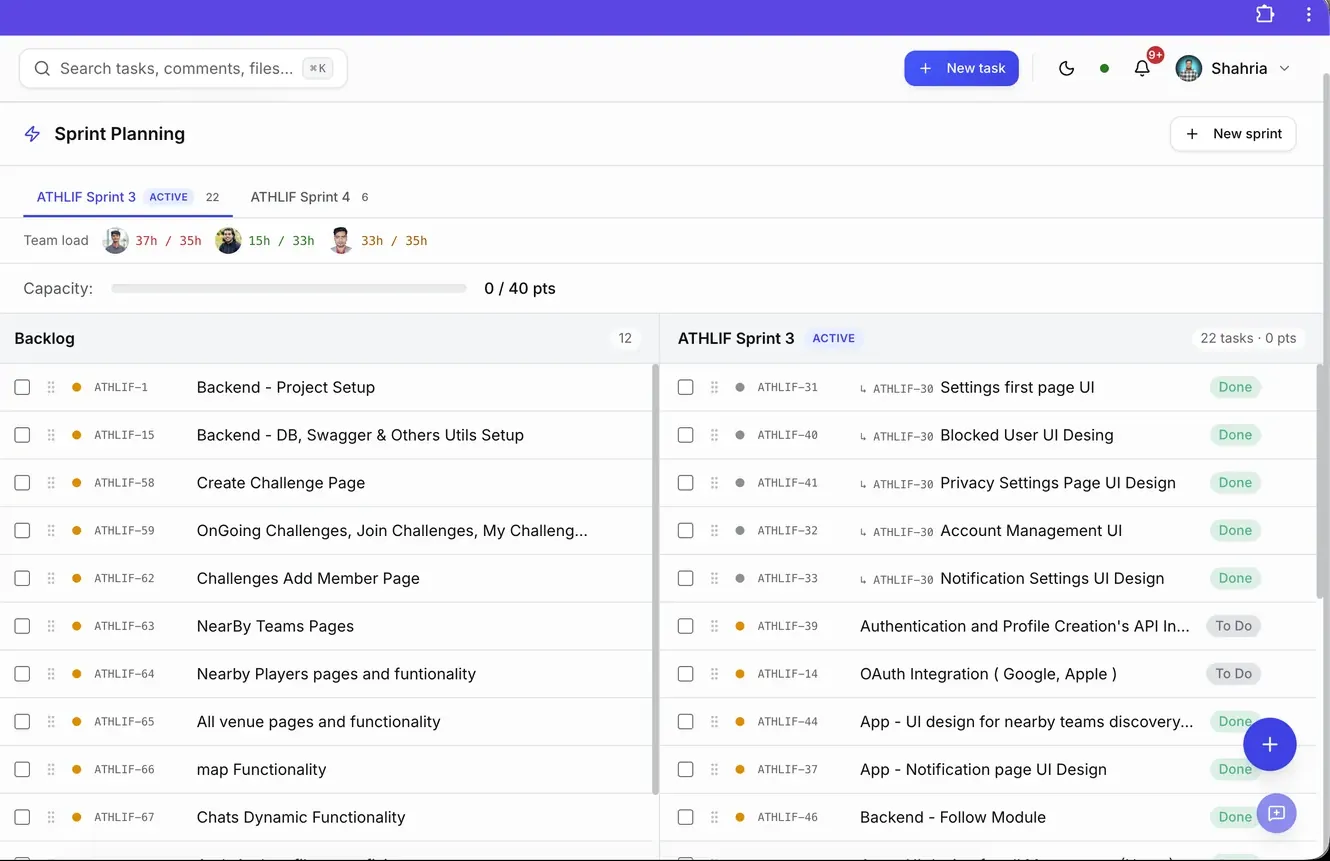
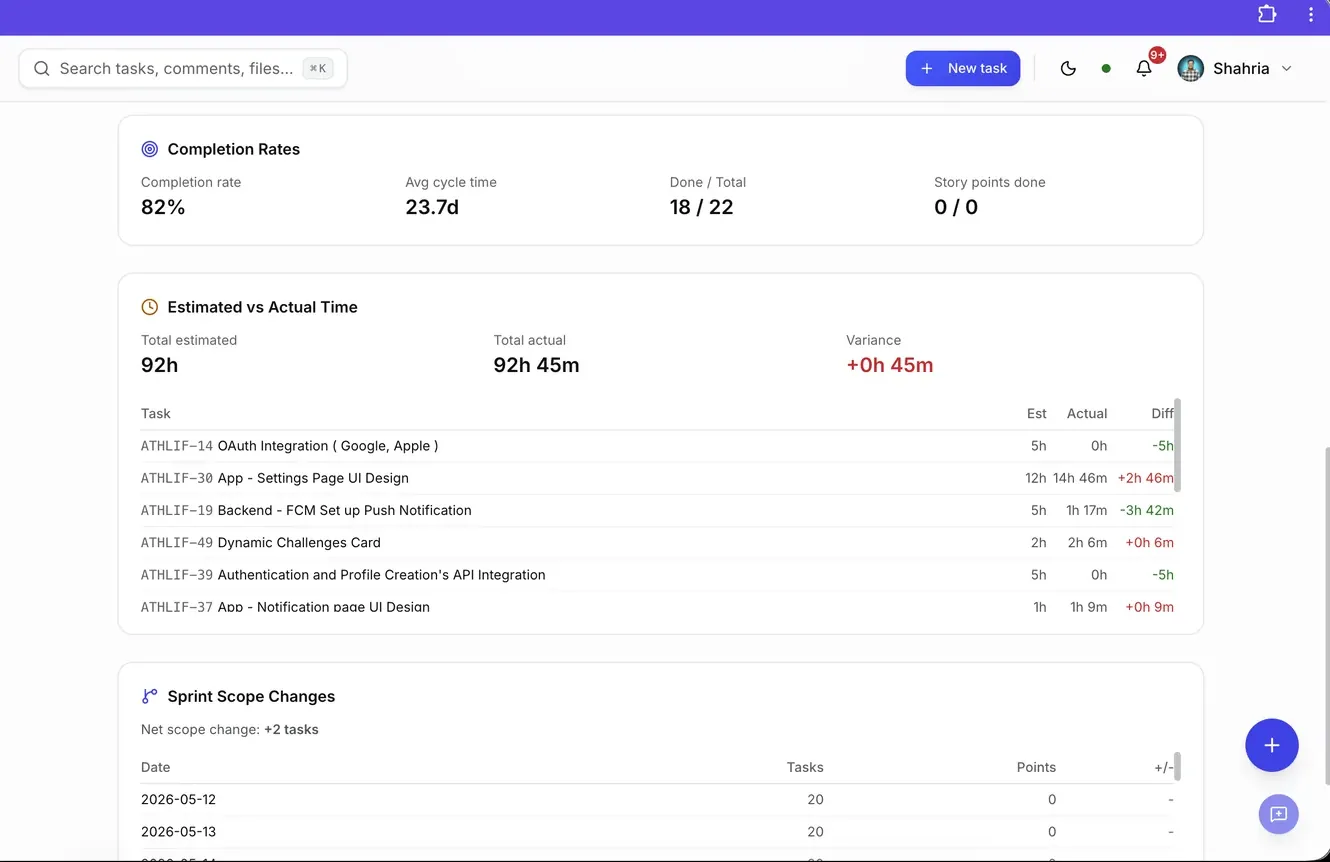
Seventeen milestones later: list, Kanban, table, calendar and Gantt views, sprints, reports, timesheets and live collaboration.
Sprint planning with per-member capacity, burndown and burnup charts, velocity and completion reports, org-wide workload, recurring tasks, custom fields, and real-time collaborative notes with version history and PDF, DOCX and Markdown export. Everything updates live over server-sent events, it installs as a PWA, and every screen ships in light and dark themes.
How a spec-first AI pipeline compresses delivery.
A disciplined pipeline, not autocomplete. AI accelerates every step; engineering discipline makes the speed safe.
Requirements are written and frozen before code, the design ships as a coded prototype, every milestone has UAT scripts that run against the live stack, and every bug fix lands with a written root-cause analysis and a durable rule, so the same class of bug cannot ship twice.
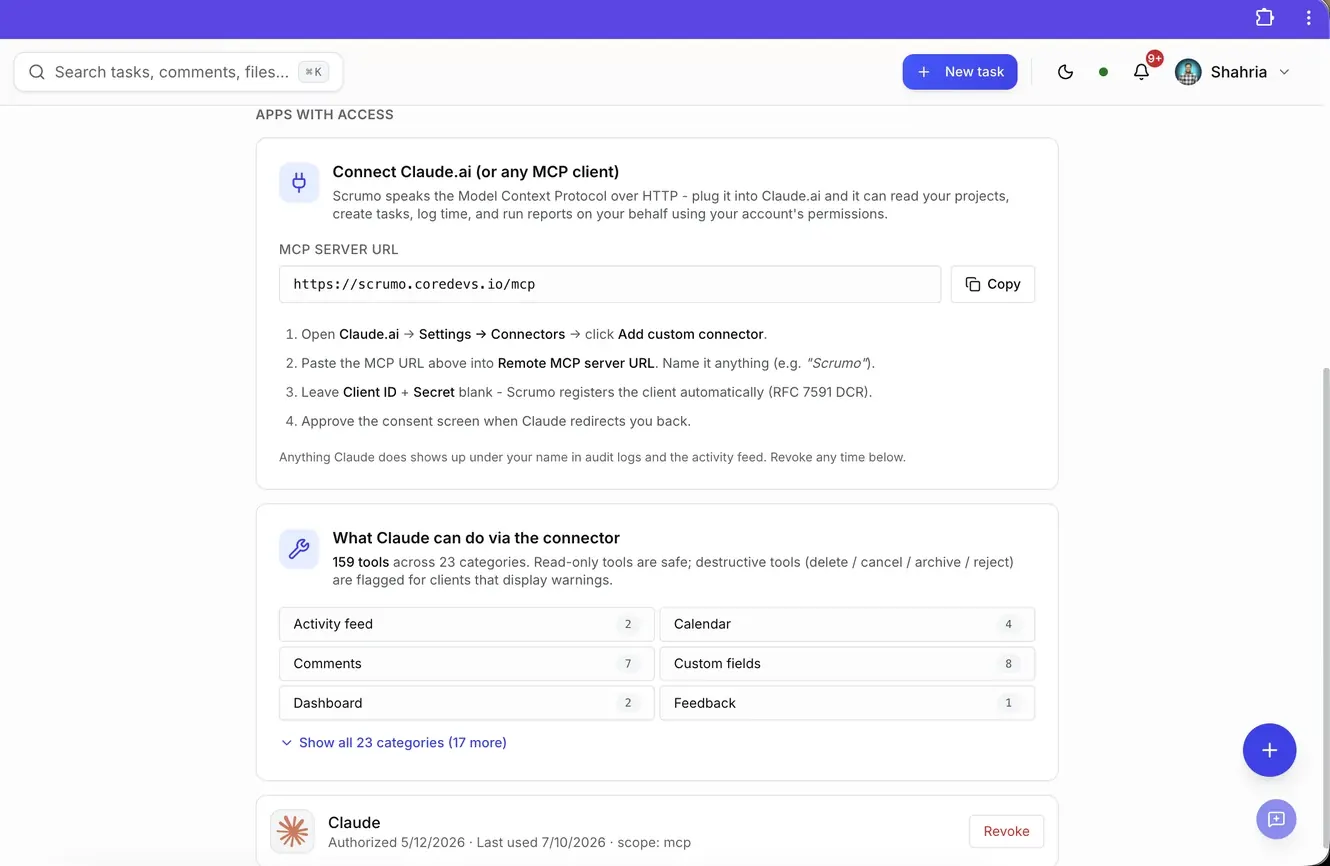
The pipeline kept compounding after launch. Scrumo now exposes its own MCP server with OAuth 2.1, so Claude and any MCP client can plan sprints, create tasks, log time and run reports directly against it. The tool my AI workflow built is now a tool my AI workflow uses.